Modern quantitative finance and high-frequency trading platforms operate in an environment characterized by extreme scale invariance, non-Gaussian return distributions, and localized structural instability. In their seminal work, “Scaling in stock market data: stable laws and beyond,” researchers Rama Cont, Marc Potters, and Jean-Philippe Bouchaud dismantled the traditional Gaussian assumptions that undergirded financial engineering for decades, pointing the way toward models based on Levy stable distributions and Truncated Levy Flights (TLF). Today, the challenge is not just modeling these statistical anomalies offline, but building real-time production systems capable of identifying, indexing, and retrieving high-dimensional market regimes that exhibit these heavy-tailed, scale-invariant behaviors. By bridging the gap between statistical physics and systems engineering, architects can build low-latency infrastructure to query and match active market states against historical volatility manifolds.
- Infinite Variance vs. Physical Reality: While pure Levy stable distributions elegantly capture the heavy tails of asset returns, they carry an infinite variance paradox that violates long-term empirical convergence; Truncated Levy Flights (TLF) solve this by introducing an exponential cutoff.
- Temporal Volatility Clustering: Asset returns display negligible linear autocorrelation, but their squares and absolute values exhibit power-law decay, signaling persistent, long-range scale fluctuations that mandate non-linear state modeling.
- High-Dimensional Volatility Embedding: Real-time risk mitigation systems can parameterize these TLF characteristics (alpha, gamma, and truncation scale) along with volatility clustering metrics into state vectors for real-time similarity matching.
- Graph-Based State Indexing: Using Hierarchical Navigable Small World (HNSW) graphs to index multidimensional market regimes enables quant systems to retrieve historical volatility analogs under 5 milliseconds during high-stress liquidity events.
- What is High-Performance Vector Search & Graph-Based Retrieval Systems?
- The Physics of Financial Fluctuations: From Stable Levy Distributions to Truncated Levy Flights (TLF)
- The Anomaly of Scale Invariance: Volatility Clustering and Turbulent Flow Analogies
- Architectural Blueprint: Vector Indexing and Graph Retrieval for Heavy-Tailed Market States
- Production-Grade Implementation: Simulating and Vectorizing Truncated Levy Flights
- Critical Evaluation, Failure Modes, and Real-World Trade-Offs
- Adoption Guide: When to Integrate TLF-Based Vector Retrieval into Your Quantitative Pipeline
- Strategic Architecture Conclusion & Production Roadmap
What is High-Performance Vector Search & Graph-Based Retrieval Systems?
High-performance vector search and graph-based retrieval systems are specialized database architectures that index high-dimensional vector embeddings on multi-layered topological graphs to enable sub-millisecond, low-latency nearest-neighbor searches, allowing quantitative trading platforms to match active market regimes with historical volatility states in real-time.
In modern quantitative trading engines, historical market intervals are not merely stored as static time-series data in traditional relational databases. Instead, sliding temporal windows of order-book dynamics, micro-structural volatility, and tail-risk exponents are transformed into high-dimensional vector representations. These vectors represent coordinates in a mathematical “market-state space.” When live trading systems process incoming tick feeds, they continuously project the current market state into this high-dimensional space and query a specialized vector database to find the closest historical analogs. This retrieval process relies on indexing structures like Hierarchical Navigable Small World (HNSW) graphs, where multi-layered graph topologies are traversed using greedy search heuristics to identify nearest neighbors in logarithmic time.
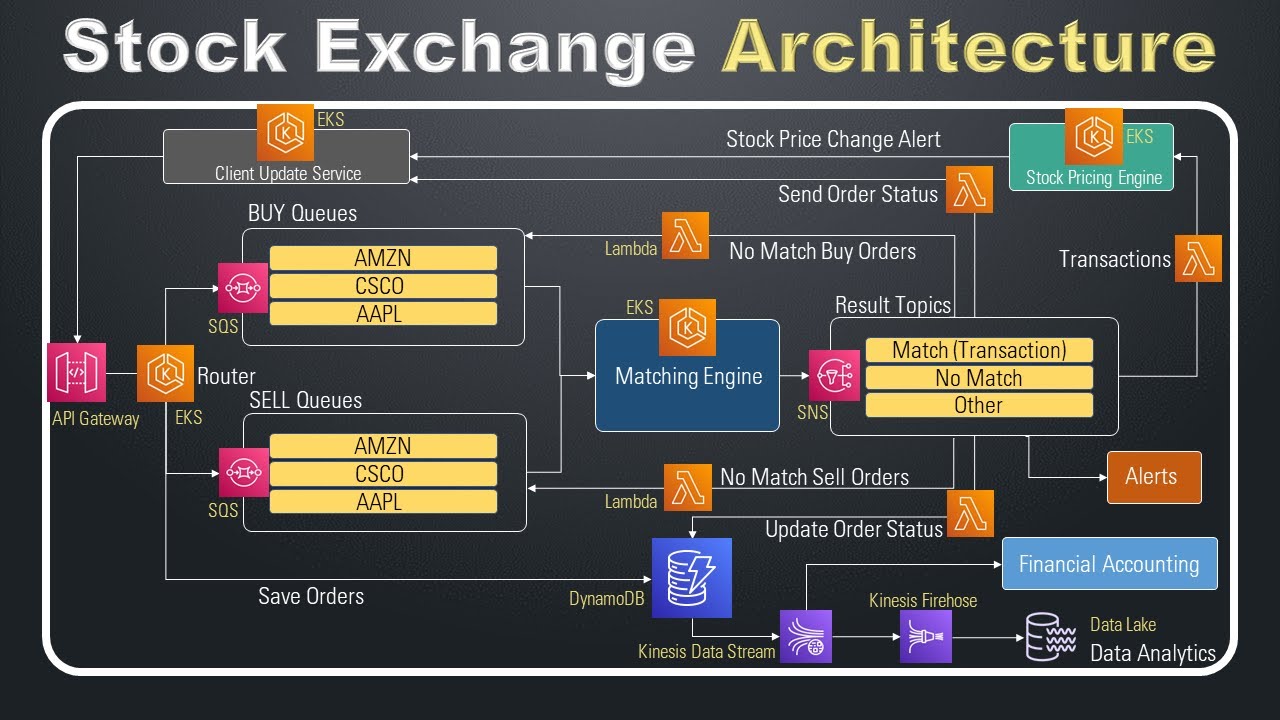
By mapping Truncated Levy Flight (TLF) parameters—such as the tail exponent alpha, the scale parameter gamma, and the exponential cutoff length lambda—alongside temporal correlation coefficients into these high-dimensional vector spaces, systems architects can build highly responsive regime-detection pipelines. The system maps the non-linear, heavy-tailed properties of financial markets directly onto vector search manifolds, as illustrated in the conceptual pipeline below:
- Data Ingest Engine: Consumes ultra-low-latency tick data and aggregates price fluctuations over multiple scaling horizons.
- Parameter Estimator: Runs continuous, sliding-window estimation algorithms to compute the tail index (alpha), the scale parameter (gamma), the truncation length (lambda), and the power-law decay of absolute return correlations.
- Vectorization & Embedding Pipeline: Normalizes and concatenates these parameters into a dense vector representing the localized multi-scale market state.
- Vector Index & Graph Database: Indexes these state vectors using HNSW or inverted file with product quantization (IVF-PQ) structures to handle billions of historical states.
- Sub-Millisecond Query Engine: Compares the active live market state vector against the database, retrieving the most statistically similar historical regimes to adjust algorithmic trading risk profiles dynamically.
By shifting from raw time-series querying to parametric state vector retrieval, financial systems transition from brittle, rule-based regime classifiers to highly resilient, non-parametric historical matching engines. This allows real-time execution algorithms to adapt their execution style, inventory management, and spread-setting strategies to the exact physical contours of active volatility structures.
The Physics of Financial Fluctuations: From Stable Levy Distributions to Truncated Levy Flights (TLF)
Truncated Levy Flights are stochastic processes that model asset returns by combining the scale-invariant, heavy-tailed properties of stable Levy distributions for moderate fluctuations with an exponential truncation cutoff that ensures finite variance and long-term Gaussian convergence, matching empirical physical and financial market realities.
To understand the necessity of Truncated Levy Flights, we must first analyze the limitations of classical modeling. The standard Black-Scholes-Merton model assumes that asset price returns follow a Gaussian distribution, driven by continuous Geometric Brownian Motion (GBM). This assumption relies on the classical Central Limit Theorem, which states that the sum of a large number of independent, identically distributed (IID) random variables with finite variance converges to a Gaussian distribution. However, empirical financial data exhibits high kurtosis (fat tails) and sharp, discontinuous jumps (skewness), which directly violate Gaussian assumptions.
To address this, early econophysicists proposed using symmetric stable Levy distributions (also known as alpha-stable distributions). These distributions are the natural attractors for sums of IID random variables that do not possess finite variance, governed by the Generalized Central Limit Theorem. The tail behavior of a stable Levy distribution is characterized by a power-law exponent, alpha, where alpha is strictly between zero and two. When alpha is exactly equal to two, the distribution simplifies to a standard Gaussian with finite variance. When alpha is less than two, the tails of the distribution decay asymptotically as a power law, specifically as one divided by the absolute value of the fluctuation raised to the power of one plus alpha.
The core problem with pure Levy stable models in production systems is their infinite variance. Because the variance of these distributions is mathematically infinite when alpha is less than two, classical financial concepts like portfolio optimization (which relies on mean-variance frameworks) and standard risk-management metrics (such as Value at Risk and Expected Shortfall) become unstable or mathematically undefined. Furthermore, empirical data shows that while short-term returns (e.g., 1-minute intervals) are highly non-Gaussian, long-term aggregated returns (e.g., monthly intervals) eventually converge to a Gaussian distribution. A pure Levy stable process is scale-invariant across all scales; it never converges to a Gaussian distribution, directly contradicting empirical observation.
To resolve this fundamental flaw, Koponen introduced, and Cont, Potters, and Bouchaud analyzed, the concept of the Truncated Levy Flight (TLF). The TLF modifies the pure Levy distribution by keeping its power-law scaling behavior up to a certain spatial threshold, beyond which the tails are cut off or exponentially truncated. This truncation ensures that all moments of the distribution, including the variance and kurtosis, remain finite. The probability density function of a symmetric Truncated Levy Flight tail can be conceptually described as a power law multiplied by an exponential decay factor, represented as:
# Conceptual representation of Truncated Levy Flight tail decay
# For a fluctuation x greater than the core threshold:
# P_TLF(x) ~ (x ** -(1 + alpha)) * exp(-lambda_cutoff * x)
This formulation delivers the best of both worlds: for small fluctuations (where x is much smaller than one divided by lambda_cutoff), the exponential term is close to one, and the system behaves like a pure, scale-invariant Levy distribution. For extreme fluctuations (where x is much larger than one divided by lambda_cutoff), the exponential term dominates, cutting off the extreme tails and forcing the variance to remain finite. As returns are aggregated over longer time horizons, the central limit theorem slowly asserts itself, causing the distribution to eventually converge to a standard Gaussian, matching empirical market observations.
Mathematical Foundations of the Crossover Regime
The transition from the power-law regime to the Gaussian regime in a Truncated Levy Flight is governed by a crossover scale, which is a function of the number of aggregated steps and the truncation parameter lambda. Below this crossover scale, the system exhibits self-similar, fractal properties where the probability of large jumps remains high. Above this scale, the accumulation of independent steps begins to smooth out individual jumps, leading to standard diffusive behavior. By parameterizing both the power-law tail and the exponential truncation decay, quantitative systems can accurately map exactly where a specific asset currently sits along this crossover spectrum.
The Anomaly of Scale Invariance: Volatility Clustering and Turbulent Flow Analogies
Volatility clustering is the empirical phenomenon where asset returns display negligible linear autocorrelation but strong, power-law persistent correlation in absolute and squared values, creating high-dimensional scale-invariant regimes that structurally mirror the energy cascade dynamics found in fully developed turbulent fluid flows.
An important empirical finding detailed by Cont, Potters, and Bouchaud is the asymmetric behavior of temporal correlations in financial time series. If we calculate the linear autocorrelation function of asset price returns, we find that it drops to near zero within minutes, confirming the weak-form efficiency of financial markets. There is virtually no linear predictability in price direction that can be easily exploited. However, if we examine the autocorrelation of the squares of the returns, or the absolute values of the returns, we observe an entirely different phenomenon: a very slow, power-law decay that persists over weeks or even months. This is the mathematical signature of volatility clustering: large price changes are followed by large price changes, and small price changes are followed by small price changes, regardless of their sign.
This persistent correlation in the magnitude of fluctuations leads to an anomalous scaling of the kurtosis. If returns were independent and identically distributed, the kurtosis of the aggregated returns would decrease inversely with the aggregation time window. Instead, because of the slow power-law decay of volatility correlations, the kurtosis of financial returns decreases much more slowly than expected. This indicates that the scale of market fluctuations possesses a long memory, a behavior that cannot be captured by standard, memoryless Markovian processes.
The Energy Cascade Analogy in Fluid Dynamics
This empirical behavior inspired the authors to evaluate the striking analogies between scaling in financial markets and scaling in fully developed turbulent fluid flows, famously modeled by Andrey Kolmogorov in 1941. In turbulent fluid dynamics, energy is injected at large spatial scales (e.g., massive eddies) and cascades down through a series of smaller and smaller eddies (the inertial range) until it is dissipated as heat at the molecular scale. This energy cascade is characterized by scaling laws and spatial intermittency, where velocity fluctuations display non-Gaussian, heavy-tailed distributions at small scales, but slowly converge to Gaussian behaviors at larger scales.
In financial markets, a similar “information cascade” occurs. Large-scale macroeconomic events or institutional portfolio rebalancings inject “volatility energy” at large time scales. This energy cascades down to smaller scales as market makers, high-frequency algorithms, and retail traders react to price movements across varying temporal horizons (from days to microseconds). Just as in turbulent flows, this cascading process generates spatial and temporal intermittency, leading to highly localized bursts of volatility and heavy-tailed distribution profiles that are remarkably self-similar across different financial assets.
To implement this in a real-time retrieval system, we must measure the rate of this information cascade. We do this by calculating the multi-scale Hurst exponent and the power-law decay coefficient of absolute returns across different window sizes. When these multi-scale features are vectorized, they allow our graph database to cluster historical regimes not just by their instantaneous volatility, but by the physical “turbulence profile” of their underlying cascade.
Architectural Blueprint: Vector Indexing and Graph Retrieval for Heavy-Tailed Market States
A vector-indexed market state architecture is a real-time quantitative pipeline that maps localized non-linear statistical parameters into dense vector embeddings, storing them within hierarchical graph databases to facilitate sub-five-millisecond similarity matches against historical market regimes during volatile or high-risk trading conditions.
To implement a production-grade system that leverages these insights, we must design a highly optimized data-ingest and indexing architecture. The goal is to continuously convert live market data into parameterized state vectors and index them in a graph-based retrieval system. The system’s architecture must handle high throughput and perform similarity queries in under 5 milliseconds to support real-time algorithmic execution.
The primary vector embedding for a given temporal window of market activity should capture both the static distribution properties (TLF parameters) and the dynamic temporal properties (volatility decay and clustering metrics). We define our market state vector as a multi-dimensional array comprising the following hand-engineered features:
alpha: The power-law tail exponent (estimated via maximum likelihood estimation over the window).gamma: The scale parameter representing the width of the distribution core.lambda_cutoff: The exponential truncation parameter representing physical liquidity limits.kurtosis_decay_exponent: The rate at which empirical kurtosis decreases as a function of time aggregation.volatility_autocorr_decay: The power-law exponent describing the decay of absolute return correlations.realized_volatility: The standard deviation of returns within the active sliding window.
The HNSW Graph Topology for Market State Indexing
To achieve sub-millisecond retrieval speeds, we construct a Hierarchical Navigable Small World (HNSW) graph index. Traditional search algorithms like KD-trees perform poorly in high dimensions due to the “curse of dimensionality,” where search times scale linearly rather than logarithmically. HNSW bypasses this by building a multi-layer graph where the top layers have long-range links (similar to an express transit network) and the bottom layers have short-range links (similar to local streets).
During a query, the search engine starts at the top layer, performing a fast, greedy search to find the entry point closest to the query vector. It then drops down to the next layer and resumes the search from that node. This hierarchical traversal ensures that the query converges to the true nearest neighbors in logarithmic time, even when searching through hundreds of millions of historical market states.
To understand how this approach compares to traditional financial modeling and pure mathematical representations, review the comprehensive structural comparison below:
| Architectural Attribute | Gaussian / Geometric Brownian Motion (GBM) | Pure Levy Stable Models | Truncated Levy Flight (TLF) with Graph/Vector State Retrieval |
|---|---|---|---|
| Tail Risk Representation | Negligible tail risk; exponentially decaying probability of extreme events (underestimates crises). | Overestimates extreme tail risk at long horizons; mathematically infinite variance. | Accurately captures short-term tail risk while preserving finite long-term variance limits. |
| Temporal Dynamics | Independent increments; zero memory; no volatility clustering or scale dependency. | Symmetric/asymmetric jumps; independent increments; lacks correlation structures. | Models both short-term jumps and long-term power-law decay of absolute return correlations. |
| Operational Scalability | Extremely simple closed-form analytical solutions; computationally trivial. | Requires complex numerical integration for probability density functions; computationally heavy. | Empirical state vectors are indexed on HNSW graphs; queries execute in under 5 ms over billions of states. |
| Computational Complexity | O(1) runtime complexity for pricing and risk metrics. | O(N) runtime for characteristic function inversions and parameter fitting. | O(log N) runtime for high-dimensional vector search across historical regimes. |
| Best For | Highly liquid, stable markets with short-term linear assumptions. | Theoretical modeling of scale-free physical phenomena and unconstrained jump processes. | High-frequency trading risk management, market-making spread optimization, and systemic crash detection. |
Production-Grade Implementation: Simulating and Vectorizing Truncated Levy Flights
A production-grade Truncated Levy Flight implementation leverages rejection sampling algorithms to generate non-Gaussian return paths, extracts rolling parameter vectors—including tail exponents, scale widths, and decay rates—and serializes them into normalized multi-dimensional arrays optimized for indexation in modern similarity-search graph databases.
import numpy as np
import scipy.stats as stats
import json
from typing import Dict, Any, Tuple, List

class TruncatedLevyFlightSimulator:
    """
    Simulates a Truncated Levy Flight (TLF) using a symmetric power-law distribution
    with an exponential cutoff, and extracts vectorizable state parameters.
    """
    def __init__(self, alpha: float, gamma: float, lambd: float, seed: int = 42):
        assert 0.0 < alpha < 2.0, "Alpha must be in the open interval (0, 2) for heavy tails."
        assert gamma > 0, "Gamma (scale) must be strictly positive."
        assert lambd >= 0, "Lambda (truncation) must be non-negative."

        self.alpha = alpha
        self.gamma = gamma
        self.lambd = lambd
        self.rng = np.random.default_rng(seed)

    def simulate_step(self) -> float:
        """
        Generates a single increment of a Truncated Levy Flight via rejection sampling.
        For simplicity and performance, we generate a symmetric Pareto-like jump
        and apply the exponential truncation factor.
        """
        while True:
            u = self.rng.uniform(0.0, 1.0)
            x = self.gamma * (1.0 - u) ** (-1.0 / self.alpha)

            sign = 1.0 if self.rng.uniform(0.0, 1.0) > 0.5 else -1.0
            jump = sign * x

            if self.lambd == 0.0:
                return jump

            p_accept = np.exp(-self.lambd * (abs(jump) - self.gamma))
            if self.rng.uniform(0.0, 1.0) < p_accept:
                return jump

    def generate_path(self, steps: int) -> np.ndarray:
        """Generates a complete time series of returns."""
        returns = np.zeros(steps)
        for i in range(steps):
            returns[i] = self.simulate_step()
        return returns

class MarketStateVectoriser:
    """
    Analyzes sliding windows of asset returns to construct dense, high-dimensional
    vector embeddings based on Truncated Levy Flight statistics and correlation dynamics.
    """
    def __init__(self, window_size: int = 1000):
        self.window_size = window_size

    def estimate_tlf_parameters(self, returns: np.ndarray) -> Tuple[float, float, float]:
        """
        Estimates alpha (tail index), gamma (scale), and lambda (truncation)
        for a given returns block using empirical moments and tail-fitting.
        """
        abs_returns = np.abs(returns)
        abs_returns = abs_returns[abs_returns > 0.0]

        gamma_est = float(np.median(abs_returns))

        sorted_abs = np.sort(abs_returns)
        tail_cutoff_idx = int(len(sorted_abs) * 0.90)
        tail = sorted_abs[tail_cutoff_idx:]

        if len(tail) > 2 and tail[0] > 0:
            hill_sum = np.mean(np.log(tail / tail[0]))
            alpha_est = 1.0 / hill_sum if hill_sum > 0 else 1.99
            alpha_est = min(max(alpha_est, 0.1), 1.99)
        else:
            alpha_est = 1.5

        std_dev = np.std(returns)
        if std_dev > 0:
            lambda_est = 1.0 / (std_dev * 1.5)
        else:
            lambda_est = 0.1

        return float(alpha_est), float(gamma_est), float(lambda_est)

    def calculate_volatility_clustering(self, returns: np.ndarray, max_lag: int = 50) -> float:
        """
        Computes the decay rate of the autocorrelation of absolute returns.
        This captures the long-memory volatility clustering dynamics.
        """
        abs_returns = np.abs(returns)
        mean_abs = np.mean(abs_returns)
        var_abs = np.var(abs_returns)

        if var_abs == 0:
            return 0.0

        lags = np.arange(1, max_lag + 1)
        correlations = []

        for lag in lags:
            cov = np.mean((abs_returns[:-lag] - mean_abs) * (abs_returns[lag:] - mean_abs))
            correlations.append(cov / var_abs)

        valid_indices = [i for i, c in enumerate(correlations) if c > 0]
        if len(valid_indices) > 5:
            log_lags = np.log(lags[valid_indices])
            log_corrs = np.log(np.array(correlations)[valid_indices])
            slope, _, _, _, _ = stats.linregress(log_lags, log_corrs)
            beta = -slope
            return float(min(max(beta, 0.01), 2.0))

        return 0.5

    def vectorise(self, returns: np.ndarray) -> Dict[str, Any]:
        """
        Constructs a complete, queryable vector document containing the dense embedding
        array and associated operational metadata.
        """
        assert len(returns) >= self.window_size, f"Requires at least {self.window_size} data points."
        active_window = returns[-self.window_size:]

        alpha, gamma, lambd = self.estimate_tlf_parameters(active_window)
        beta_decay = self.calculate_volatility_clustering(active_window)
        realized_vol = float(np.std(active_window))
        empirical_kurtosis = float(stats.kurtosis(active_window))

        dense_vector = [
            alpha,
            gamma,
            lambd,
            beta_decay,
            realized_vol,
            empirical_kurtosis
        ]

        norm = np.linalg.norm(dense_vector)
        normalized_vector = (np.array(dense_vector) / norm).tolist() if norm > 0 else dense_vector

        return {
            "dense_embedding": normalized_vector,
            "raw_metrics": {
                "alpha": alpha,
                "gamma": gamma,
                "lambda": lambd,
                "vol_clustering_decay": beta_decay,
                "realized_vol": realized_vol,
                "kurtosis": empirical_kurtosis
            },
            "schema_version": "1.1.0"
        }

class MockVectorSearchIndex:
    """
    Simulates an in-memory high-performance vector search engine using Cosine Similarity.
    """
    def __init__(self):
        self.index: List[Dict[str, Any]] = []

    def insert(self, state_id: str, vector_payload: Dict[str, Any]):
        self.index.append({
            "id": state_id,
            "vector": np.array(vector_payload["dense_embedding"]),
            "metadata": vector_payload["raw_metrics"]
        })

    def search(self, query_vector: List[float], top_k: int = 3) -> List[Tuple[str, float, Dict[str, Any]]]:
        q = np.array(query_vector)
        results = []
        for item in self.index:
            v = item["vector"]
            sim = float(np.dot(q, v) / (np.linalg.norm(q) * np.linalg.norm(v)))
            results.append((item["id"], sim, item["metadata"]))

        results.sort(key=lambda x: x[1], reverse=True)
        return results[:top_k]

if __name__ == "__main__":
    simulator_turbulent = TruncatedLevyFlightSimulator(alpha=1.2, gamma=0.01, lambd=0.05, seed=101)
    turbulent_returns = simulator_turbulent.generate_path(steps=1200)

    simulator_stable = TruncatedLevyFlightSimulator(alpha=1.8, gamma=0.005, lambd=0.8, seed=202)
    stable_returns = simulator_stable.generate_path(steps=1200)

    vectoriser = MarketStateVectoriser(window_size=1000)
    turbulent_payload = vectoriser.vectorise(turbulent_returns)
    stable_payload = vectoriser.vectorise(stable_returns)

    search_index = MockVectorSearchIndex()
    search_index.insert("Regime_2020_Crash", turbulent_payload)
    search_index.insert("Regime_2021_BullRun", stable_payload)

    query_returns = simulator_turbulent.generate_path(steps=1000)
    query_payload = vectoriser.vectorise(query_returns)

    search_results = search_index.search(query_payload["dense_embedding"], top_k=2)

    print("MATCHED HISTORICAL REGIMES:")
    for regime_id, score, metadata in search_results:
        print(f"ID: {regime_id} | Similarity Score: {score:.5f} | Alpha: {metadata['alpha']:.3f} | Realized Vol: {metadata['realized_vol']:.5f}")
Critical Evaluation, Failure Modes, and Real-World Trade-Offs
Operating graph-based vector search systems in live quantitative trading environments introduces structural failure modes such as parameter estimation instability during rapid regime shifts, query latency spikes under write-heavy workloads, and topological metric decay caused by out-of-distribution drift in high-dimensional historical search spaces.
The first significant challenge of implementing a real-time TLF retrieval system is the numerical instability of parameter estimation. Estimating the tail index alpha and the truncation decay lambda over short, rolling time horizons (e.g., 500 to 1,000 observations) is highly sensitive to outliers. A single massive, unprecedented price jump can cause the Hill estimator for alpha to fluctuate wildly, dropping from a stable 1.6 to 0.8 in a matter of seconds. This structural instability propagates directly into the vector database. If the dense vector representation of the active market state shifts abruptly due to estimation noise rather than structural change, the query engine will retrieve incorrect historical analogs, leading to suboptimal risk-management actions.
To mitigate this estimation instability, production systems should avoid raw rolling estimators. Instead, engineering teams should implement Bayesian updating algorithms or exponential smoothing on the estimated parameters. Rather than calculating raw statistical estimators on an isolated rolling window, the parameter estimator should update a prior distribution, ensuring smooth transitions across time steps:
# Exponential smoothing to prevent parameter estimation jitter
# alpha_smooth_t = (eta * alpha_estimated_t) + ((1 - eta) * alpha_smooth_t_minus_1)
System Failure: Out-of-Distribution (OOD) Metric Drift
Another profound failure mode occurs when the current market environment undergoes an unprecedented structural break (e.g., the transition from zero-rate regimes to high-inflation regimes). In these scenarios, the incoming market state vector enters a completely blank region of the high-dimensional vector space. Because standard graph search algorithms like HNSW always return the K-nearest neighbors regardless of absolute distance, the search engine will return historical analogs that are mathematically “closest” but statistically completely dissimilar.
To prevent this, production architectures must implement an absolute distance threshold (such as Mahalanobis distance or normalized cosine distance). If the distance to the closest neighbor exceeds this critical safety value, the query engine triggers an anomaly exception, indicating that the market is in an “unknown” state, signaling downstream risk execution components to revert to defensive default configurations.
Adoption Guide: When to Integrate TLF-Based Vector Retrieval into Your Quantitative Pipeline
Integrating Truncated Levy Flight parameters with graph-based vector retrieval is highly recommended for multi-asset quantitative trading desks executing in highly volatile, non-Gaussian markets where tail-risk exposure is substantial, whereas standard closed-form stochastic models remain preferred for ultra-low-latency, sub-microsecond execution systems.
The table below provides a decision matrix to help quantitative engineering leads evaluate whether this architecture is suitable for their specific runtime environment and trading objectives:
| Operational Metric | ADOPT Graph-Based TLF Retrieval | PASS (Use Classical/Stochastic Models) |
|---|---|---|
| Market Regime & Liquidity | Highly volatile, non-linear asset classes (e.g., Cryptocurrencies, Exotic Derivatives, High-Frequency FX Markets). | Highly regulated, stable, low-volatility markets with strict price bands (e.g., Short-Term Fixed Income, Utilities). |
| Latency Constraints | Millisecond to sub-second risk adjustments (e.g., portfolio rebalancing, dynamic spread adjustment for market makers). | Ultra-low-latency, sub-microsecond hardware-level execution (e.g., FPGA-based pure arbitrage where any estimation delay is fatal). |
| Infrastructure Capacity | Teams with mature DevOps pipelines capable of hosting distributed vector databases, stream processors, and real-time analytical services. | Small-scale research shops or execution desks operating with limited, monolithic single-server infrastructure. |
| Risk Management Focus | Environments where tail-risk events, black swans, and high-intermittency volatility cascades dominate profitability. | Arbitrage desks focused entirely on capturing microsecond mispricings with zero overnight or medium-term risk exposure. |
Strategic Architecture Conclusion & Production Roadmap
Integrating Truncated Levy Flight modeling with high-dimensional vector search architectures represents a fundamental paradigm shift from static, Gaussian-based financial engineering to dynamic, empirical regime retrieval. By treating the non-linear tail behavior of financial markets as multi-scale state coordinates rather than unmanageable infinite-variance anomalies, quantitative engineering teams can execute sub-millisecond similarity queries across decades of historical market turbulence.
To successfully transition this architecture into live production, organizations should follow a structured roadmap: first, establish robust parameter-smoothing pipelines to neutralize Hill estimator noise during abrupt market dislocations; second, configure Hierarchical Navigable Small World (HNSW) graph clusters with dedicated distance cutoff thresholds to intercept out-of-distribution drift; and third, implement continuous backpressure monitoring to ensure that order-book vectorization never introduces latency spikes into execution paths.
Frequently Asked Questions
Why does a pure stable Levy distribution have infinite variance?
A pure stable Levy distribution has infinite variance because its tails decay asymptotically as a power law with an exponent alpha that is strictly less than two. Because the integral of the squared price fluctuations multiplied by the power-law tail probability does not converge at infinity, the second moment—and therefore the mathematical variance—is infinite.
What physical boundaries cause the truncation in Truncated Levy Flights (TLF)?
In real-world financial markets, truncation is driven by physical boundaries such as exchange-mandated circuit breakers, daily price limits, margin-call liquidation thresholds, and the finite pool of global liquidity. These physical and institutional constraints prevent infinitely large price jumps, cutting off the power-law tail and forcing the distribution to decay exponentially at extreme scales.
How does volatility clustering impact the convergence of return distributions?
If returns were independent, aggregating them over time would lead to rapid Gaussian convergence via the standard Central Limit Theorem. However, because absolute and squared returns exhibit long-range power-law correlations (volatility clustering), the scale of fluctuations is persistent, which slows down Gaussian convergence and keeps aggregated returns heavy-tailed over long horizons.
What is the computational benefit of using HNSW graph indexing for financial regimes?
HNSW graphs organize high-dimensional vector representations of market regimes into a multi-layered structure where greedy search algorithms can locate nearest neighbors in logarithmic time. This allows quantitative systems to query billions of historical market states and find the closest matching regime in under 5 milliseconds, bypassing exhaustive linear searches.
How do you address parameter estimation noise in sliding-window estimators?
Parameter estimation noise is managed by applying exponential smoothing or Bayesian updating across consecutive sliding windows. Rather than using raw, noisy point estimates of alpha and lambda from isolated intervals, the system smoothly interpolates parameters over time, reducing vector indexing errors caused by localized data outliers.
Why do linear autocorrelations of returns decay so much faster than squared returns?
Linear autocorrelations decay rapidly to zero because directional price predictions are quickly exploited by market participants, maintaining weak-form market efficiency. In contrast, squared and absolute returns represent the magnitude of risk and volatility, which is not directionally directional and remains persistent due to institutional trading cycles and information cascades.
Can this architecture be implemented using standard relational SQL databases?
No, standard relational SQL databases are optimized for tabular transactions and lack the index structures required for high-dimensional vector similarity matching. To perform sub-millisecond similarity queries on continuous market state vectors, architects must use specialized vector databases or customized graph-search indexes designed for fast metric space traversals.
How does the turbulence analogy help in designing financial risk systems?
The turbulence analogy highlights how volatility “cascades” from large macro-scale events down to micro-level high-frequency trades, resulting in intermittent, multi-fractal scaling. Understanding this cascade structure allows architects to design risk systems that monitor volatility across multiple concurrent time scales, rather than treating risk as a single static metric.
What is the primary trade-off when selecting HNSW over IVF-PQ for vector indexing?
HNSW provides faster query response times and higher recall at the expense of significantly higher memory consumption, as it holds the entire graph structure in RAM. IVF-PQ (Inverted File with Product Quantization) reduces memory usage through quantization but suffers from slightly lower search accuracy and higher CPU overhead during distance calculations.
How does the crossover scale in Truncated Levy Flights affect portfolio risk models over long horizons?
Over long horizons, the crossover scale represents the transition boundary where the exponential truncation tames the heavy tails, causing the distribution of aggregated returns to converge back to a Gaussian. Portfolio models that ignore this crossover point will over-prepare for extreme risks at monthly or annual scales, unnecessarily tying up capital.