OpenAI math group in Risky Push on Urgent Rules
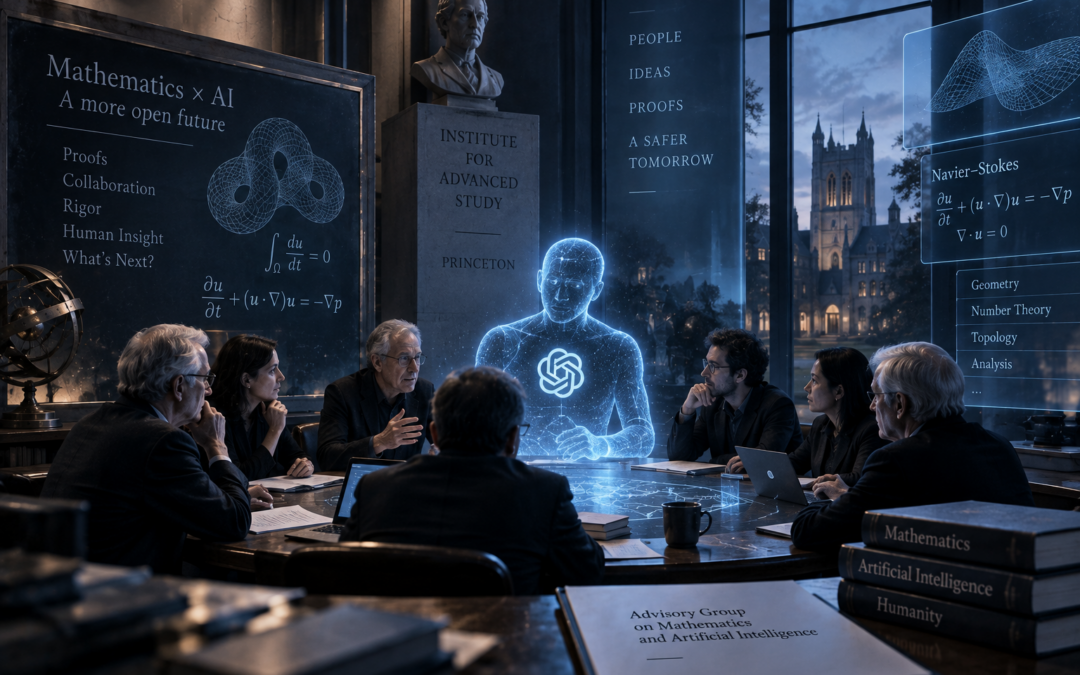
OpenAI has set up a new independent council to guide its mathematical work. The new OpenAI math group operates out of the Institute for Advanced Study in Princeton, New Jersey. The team carries the formal title of the Advisory Group on Mathematics and...
Meta Muse app Race is an Urgent Privacy Warning
The Meta Muse app has officially outpaced ChatGPT in early mobile app adoption. Fresh figures reveal that the new AI tool attracted more downloads and daily users in its first 12 days than OpenAI saw during its mobile debut. Market intelligence data...
NVIDIA SoL-Pi is a Powerful Push for Risky Data
Autonomous coding agents now handle complex software engineering tasks for hours at a time. Each file edit, command execution, and test log flows directly back into model memory. As context expands, token traffic surges and costs escalate quickly. To solve this...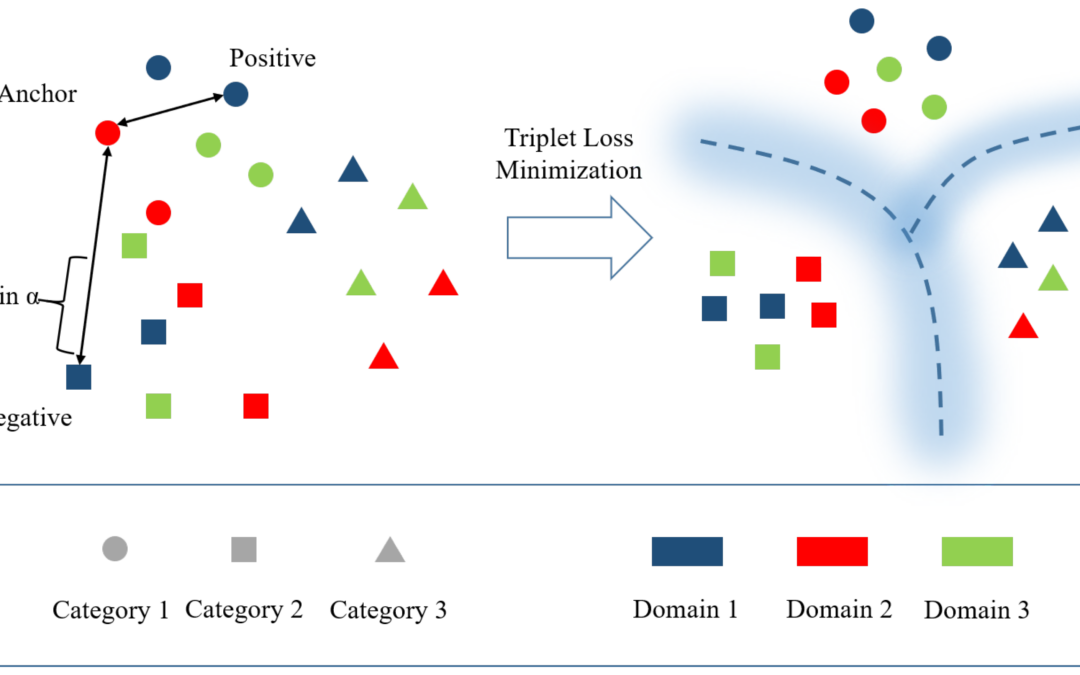
Local-Margin Triplet Loss: Architecture Deep Dive
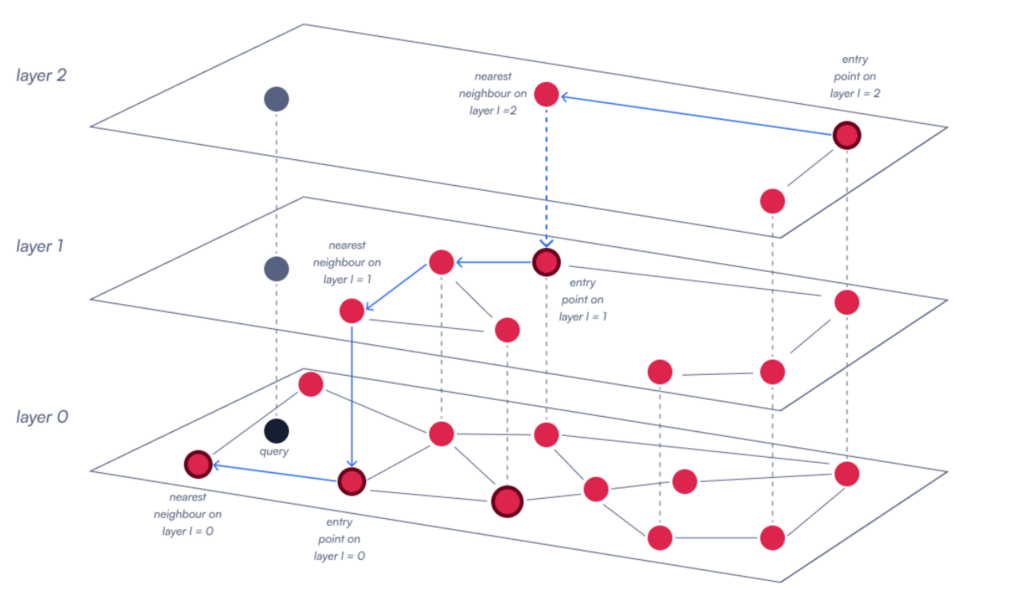
Modern machine learning architectures frequently rely on deep representation learning coupled with non-parametric classifiers to solve complex visual recognition and retrieval tasks, particularly in domains constrained by sparse training data. Standard deep learning...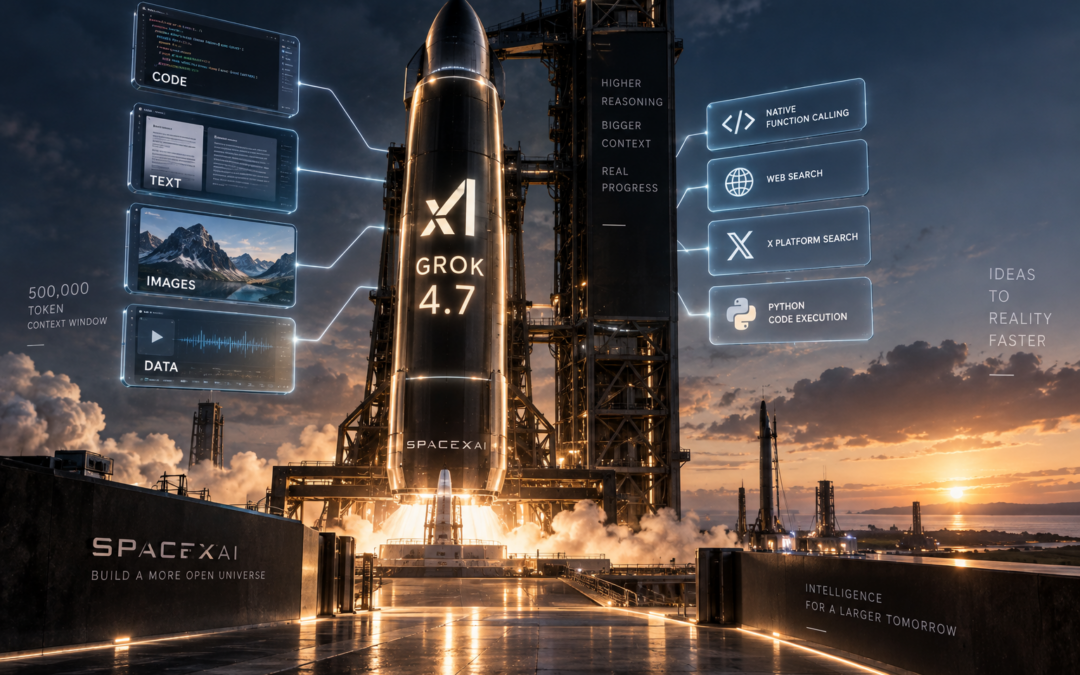
Revolutionary Grok 4.7 is a Risky Push for Data
SpaceXAI has officially launched Grok 4.7, its newest flagship model for software coding, agentic workflows, and complex knowledge tasks. Now, developers can test the system across multiple coding environments and cloud gateways. The release lands as an upgrade over...
How Strands harness is a Proven Risky New Deal
The Strands Agents team at AWS released Strands harness today under the Apache 2.0 license. This open-source agent framework cuts token costs by 28% across six industry benchmarks while matching leading accuracy numbers. Developers often face steep hurdles when moving...
Qwen-Image-2.1 is a Powerful New Warning on Rules
Alibaba has officially unveiled Qwen-Image-2.1, a unified vision model that pairs text-to-image generation with image editing. The release marks a major architectural update for the open-weight AI space. In the past, teams had to maintain two separate systems to...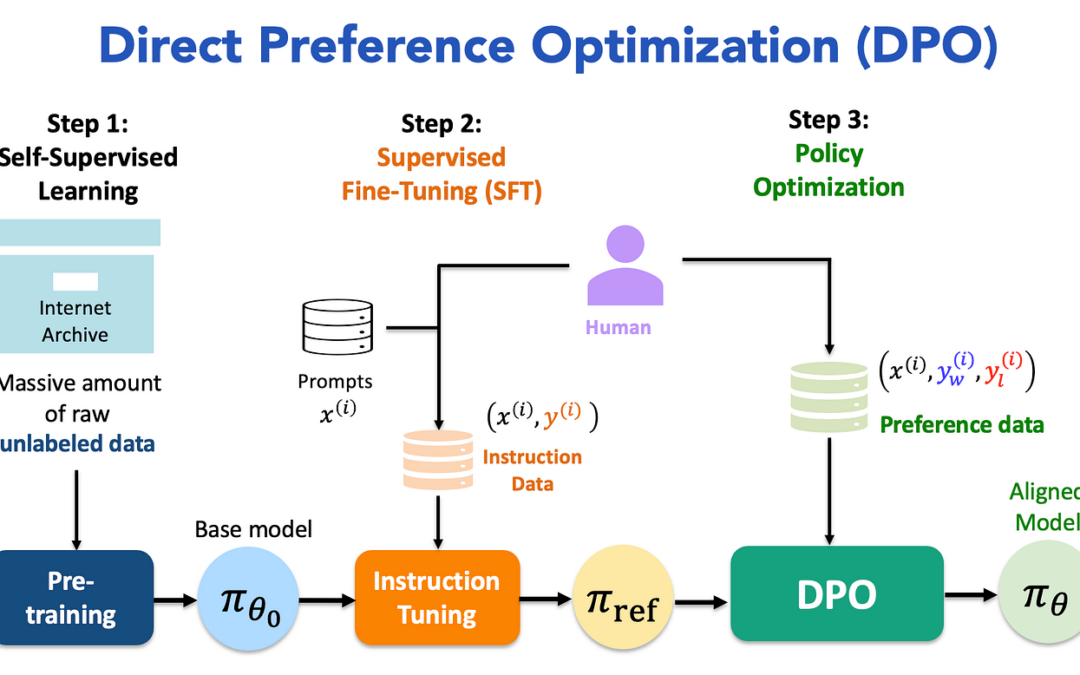
Direct Preference Optimization: Production Deep Dive
The quest to align large language models (LLMs) with human values, preferences, and safety constraints has historically relied on Reinforcement Learning from Human Feedback (RLHF). While highly effective, the traditional RLHF pipeline—exemplified by algorithms like...